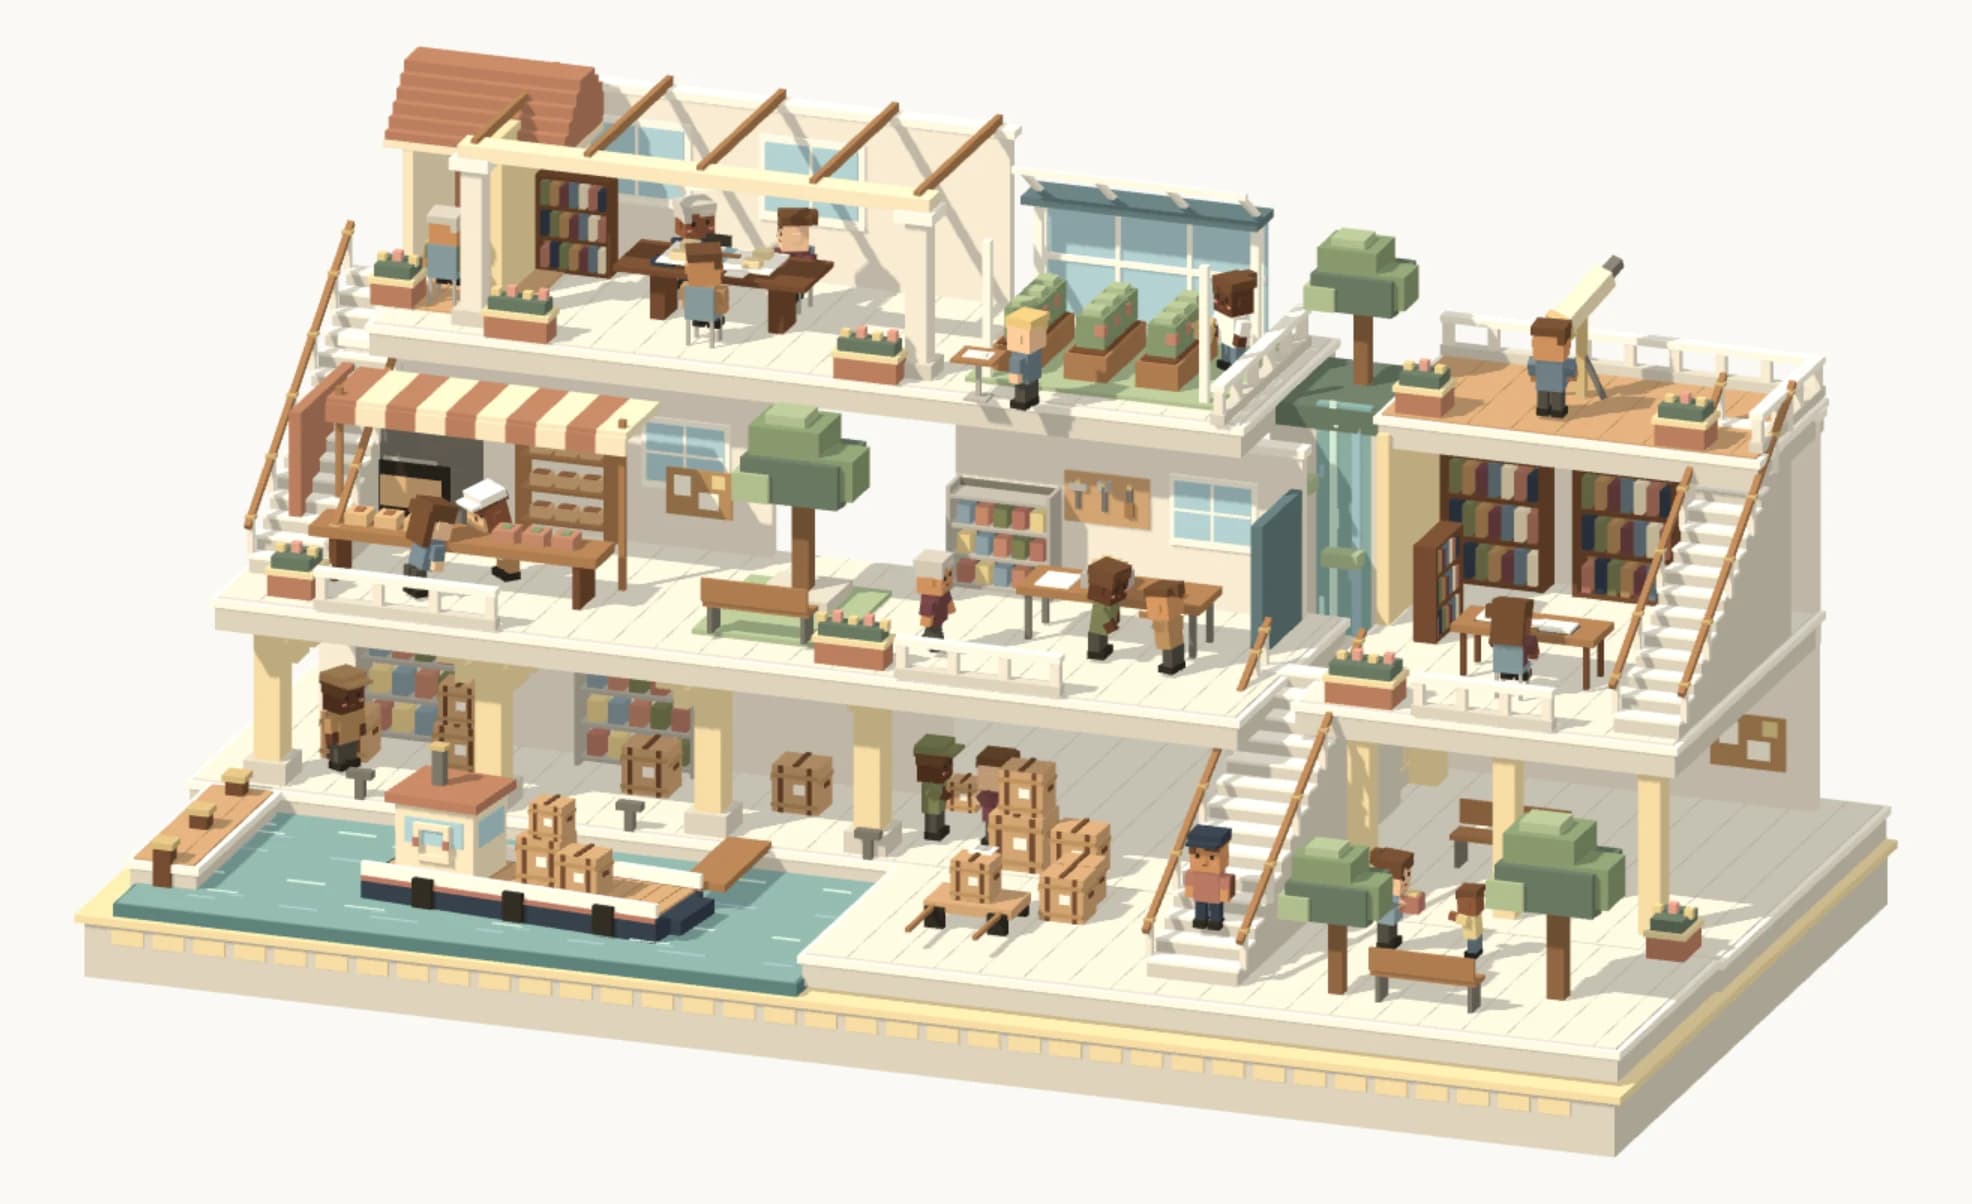
Introducing Terrarium-1
Our ultra long horizon, multi-agent platform for studying how language models behave in complex worlds.
As we enter the agentic era, AI is being integrated into our workflows at a rapid pace. We built Terrarium-1 to facilitate AI’s transition from the Lab and into deployment. For example, frontier models are traditionally developed in isolation yet are deployed in combination. Moreover, when built for short, functional, task execution they don't live with the consequences of their earlier choices. At Align Worlds we study how open and closed models behave in long running, complex, dynamic systems. We investigate how they interact with each other and with us. In turn, the models learn how their decisions play out over time so they can become a reliable coworker and performant in society. Less autonomous agent, more helpful Sherpa.
Terrarium-1 builds persistent worlds where language models are the residents. It runs one continuous session so agents have to live with the results of their decisions. Its open ended nature introduces uncertainty, its endless possibility space tests broad skills (instead of single turn tasks) and its dynamic interactivity surfaces softer attributes such as judgement, persuasion and deception, alongside the characteristics and preferences of each model. Collectively this generates unseen effects, which we think are important to uncover pre-deployment.
Worlds that leave the decisions open
From Terrarium-1 scenariosAn open classroom
A private disclosure
A consequential decision
The Terrarium-1 causal engine generates complex custom scenarios which are representative of your environment (e.g. village, business, hospital, school). It enforces constraints instead of instructions and the models are encouraged to explore with no clear sub-rewards.
Terrarium-1's rich representations provide a safe environment for models to practise and improve while enabling us to observe, probe, stress test and create edge cases in order to identify current shortfalls, alongside second and third order effects. Meanwhile, our long running approach enables Terrarium-1 to capture emergent behaviour and identify when continuity fails, models spiral or collapse occurs.
Multi-model runs not only reveal how different policies interact, but also the impact of distillation on affinity, which search spaces overlap and how models are influenced, etc. From that we can discern what model groupings are truly diverse, which pairings are best for reviews, which models rank adherence over adaptability, which are more user centric than policy optimised or are more competitive than collaborative, and so forth.
Our research-driven approach enables us to baseline off-the-shelf model capabilities and then evaluate the impact of different interventions (such as a new policy, rubric, fine tune, harness, reward model, etc.). Our ledger captures current strengths, alongside areas to improve and celebrates safe progress. Each scenario can measure the specific attributes required to design the optimal multi-agent configuration for your particular task and assess the deployment readiness of your solution.
Follow a run, then examine any moment
Reconstruct a saved moment
- World
- Facts, locations and access
- Agents
- Private context and memory
- Ledger
- Actions, conversations and token use
The Terrarium-1 emulator provides full experimental control and the ledger preserves the full run. Together this enables a rigorous, reproducible testing environment that can be run on demand and replayed. Terrarium-1 captures the reasoning behind each decision and surfaces key insights alongside core analytics, including tokens used per outcome (ROI).
Help us Align Worlds! Email us at hello@alignworlds.com.